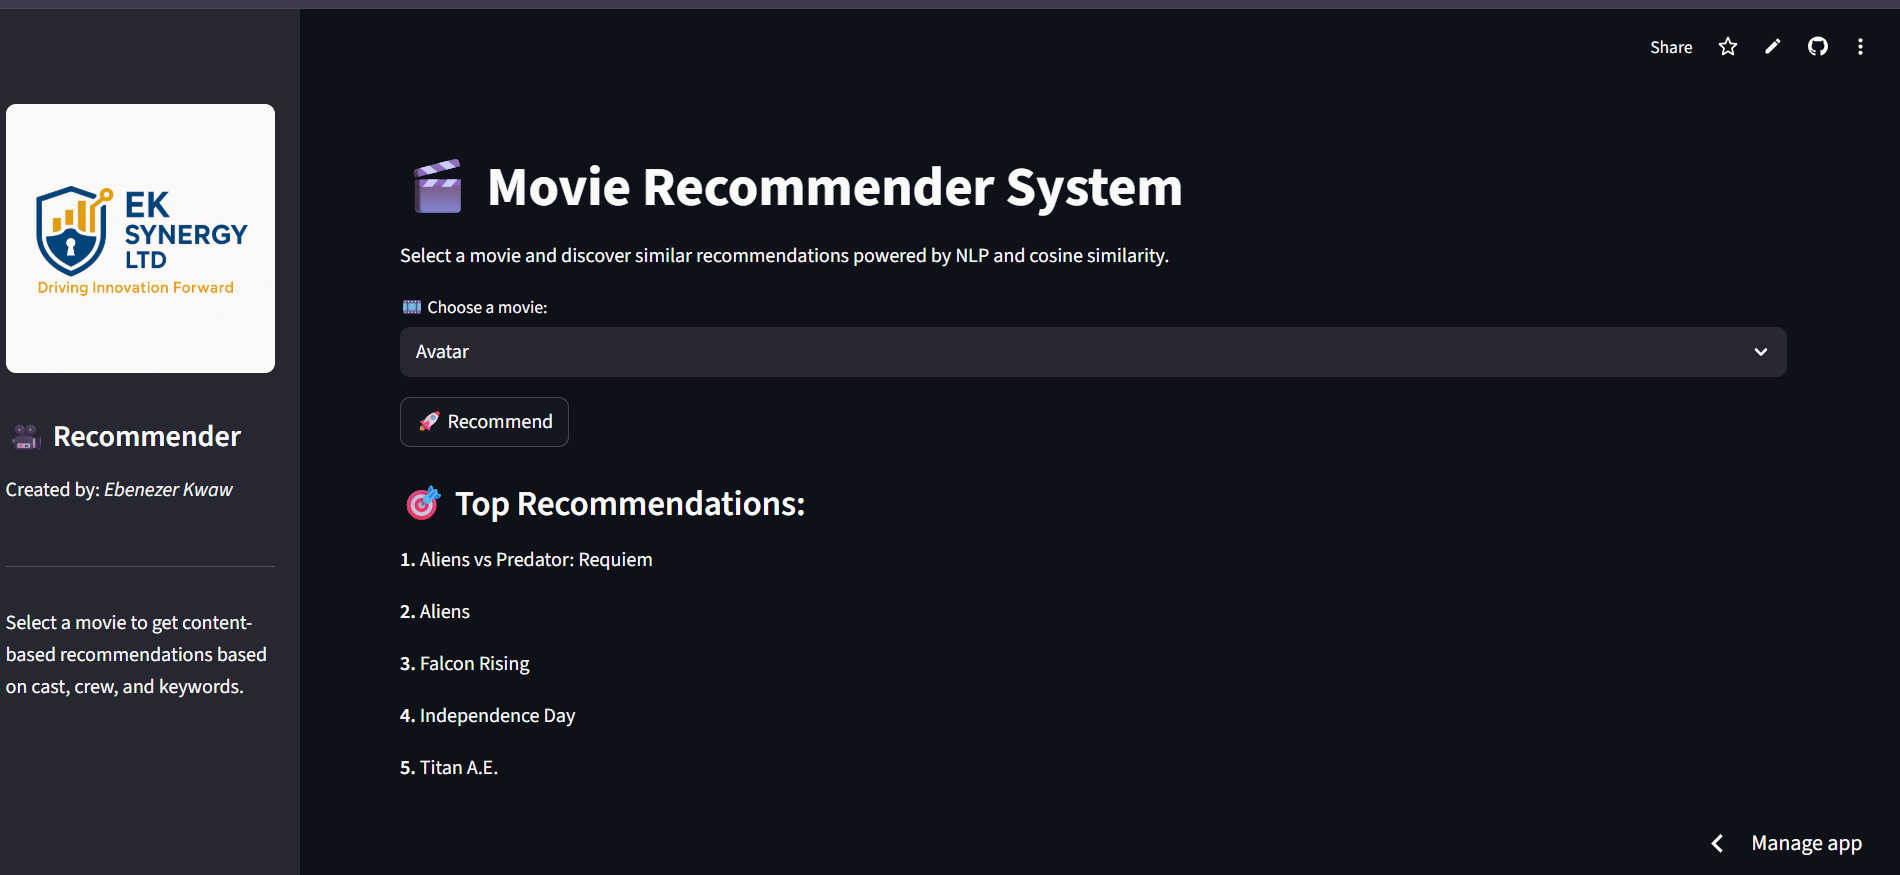
A content-based recommendation prototype that suggests similar films using movie metadata.
The challenge
Large catalogues make discovery difficult, while ordinary search may not surface titles with similar themes, genres or creative attributes.
The strategy
Represent selected movie metadata as vectors and use cosine similarity to retrieve the most similar titles without requiring personal viewing history.
My contribution and execution
- Merged the TMDB 5000 Movies and Credits datasets.
- Prepared overview, genre, keyword, cast and director features.
- Used vectorization and cosine similarity to rank related movies.
- Built a Streamlit interface that returns five recommendations from a selected title.
Tools and methods
Python, Pandas, CountVectorizer, cosine similarity, TMDB datasets and Streamlit
Outcome, evidence and limitations
The prototype demonstrates a clear content-based workflow. Its recommendations were not evaluated through live user behavior, and future work could add collaborative or hybrid filtering, ratings and a broader catalogue.
Why this project matters
This project demonstrates how I translate a practical problem into a structured strategy, prototype or analytical workflow. It also records the limits of the current work and the next validation needed before broader use.
← Back to all insights